Download the PHP package google-gemini-php/laravel without Composer
On this page you can find all versions of the php package google-gemini-php/laravel. It is possible to download/install these versions without Composer. Possible dependencies are resolved automatically.
Download google-gemini-php/laravel
More information about google-gemini-php/laravel
Files in google-gemini-php/laravel
Package laravel
Short Description Google Gemini PHP for Laravel is a supercharged PHP API client that allows you to interact with the Google Gemini AI API
License MIT
FAQ
Example:

In general, it is recommended to use always a project to download your libraries. In an application normally there is more than one library needed.

- Some hosting areas are not accessible by a terminal or SSH. Then it is not possible to use Composer.
- To use Composer is sometimes complicated. Especially for beginners.
- Composer needs much resources. Sometimes they are not available on a simple webspace.
- If you are using private repositories you don't need to share your credentials. You can set up everything on our site and then you provide a simple download link to your team member.
- Simplify your Composer build process. Use our own command line tool to download the vendor folder as binary. This makes your build process faster and you don't need to expose your credentials for private repositories.
Informations about the package laravel

Gemini PHP for Laravel is a community-maintained PHP API client for the Gemini API, with a facade, configuration and testing helpers for Laravel. It covers text, image, video, audio and document input, streaming, chats, structured output, function calling, built-in tools (Google Search, Google Maps, URL context, File Search, code execution), image and speech generation, thinking models, files, context caching, file search stores, embeddings and models, and ships with a fake client for testing.
- Fatih AYDIN github.com/aydinfatih
- Vytautas Smilingis github.com/Plytas
This package is a Laravel wrapper around google-gemini-php/client. For more information, take a look at that repository.
Table of Contents
- Prerequisites
- Setup
- Installation
- Setup your API key
- Upgrade to 2.0
- Usage
- Generating Content
- Text-only Input
- Text-and-image Input
- Text-and-video Input
- Media Resolution
- Image Generation
- Multi-turn Conversations (Chat)
- Chat with Streaming
- Stream Generate Content
- Structured Output
- Function Calling
- Code Execution
- Grounding with Google Search
- Grounding with Google Maps
- Grounding with File Search
- URL Context
- Server-side Tool Invocations
- System Instructions
- Speech Generation
- Thinking Mode
- Count Tokens
- Response Metadata
- Configuration
- File Management
- File Upload
- List Files
- Get File Metadata
- Delete File
- Cached Content
- Create Cached Content
- List Cached Content
- Get Cached Content
- Update Cached Content
- Delete Cached Content
- Use Cached Content
- File Search Stores
- Create File Search Store
- Get File Search Store
- List File Search Stores
- Delete File Search Store
- File Search Documents
- Upload File Search Document
- Import File Search Document
- Get Operation
- Get File Search Document
- List File Search Documents
- Delete File Search Document
- Embeddings
- Models
- List Models
- Get Model
- Generating Content
- Troubleshooting
- Error Handling
- Empty Responses
- Timeout
- Testing
Prerequisites
To complete this quickstart, make sure that your development environment meets the following requirements:
- Requires PHP 8.2+
- Requires Laravel 9, 10, 11, 12 or 13
The features in this README need version 2.8 or later of google-gemini-php/client, which requires PHP 8.2. On PHP 8.1, Composer installs version 2.7 of the client.
Setup
Installation
First, install Gemini via the Composer package manager:
Next, execute the install command:
This creates a config/gemini.php configuration file and adds an empty GEMINI_API_KEY variable to your .env and .env.example files.
You can also define the following environment variables:
Setup your API key
To use the Gemini API, you'll need an API key. If you don't already have one, create a key in Google AI Studio.
Upgrade to 2.0
Starting 2.0 release this package will work only with Gemini v1beta API (see API versions).
To update, run this command:
This release introduces support for new features:
- Structured output
- System instructions
- File uploads
- Function calling
- Code execution
- Grounding with Google Search
- Cached content
- Thinking model configuration
- Speech model configuration
\Gemini\Enums\ModelType enum has been deprecated and will be removed in next major version. Together with this Gemini::geminiPro() and Gemini::geminiFlash() methods have been deprecated as well.
We suggest using Gemini::generativeModel() method and pass in the model string directly. All methods that had previously accepted ModelType enum now accept a BackedEnum. We recommend implementing your own enum for convenience.
There may be other breaking changes not listed here. If you encounter any issues, please submit an issue or a pull request.
Usage
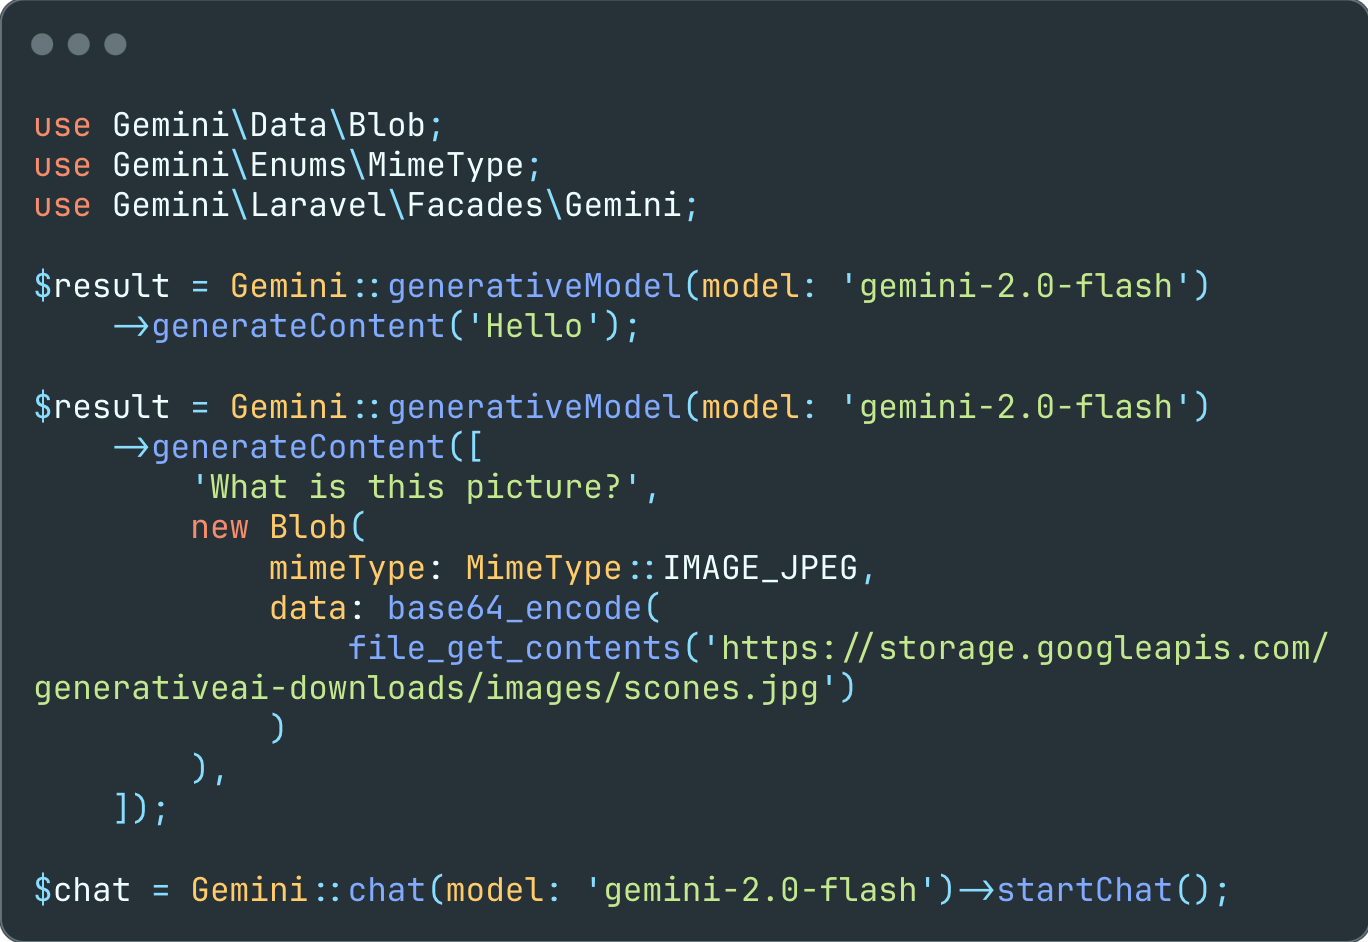
Use the Gemini facade to send a prompt to a model:
Model names change often. Check the models documentation or list the models available to your API key. The examples in this README use gemini-2.5-flash.
The API key, base URL and request timeout are read from config/gemini.php. The client is also bound in the container as Gemini\Contracts\ClientContract, so it can be injected:
Generating Content
For a complete list of supported input formats and methods, see the models documentation.
Text-only Input
Generate a response from the model given an input message.
Text-and-image Input
Generate responses by providing both text prompts and images to the Gemini model.
Text-and-video Input
Process video content and get AI-generated descriptions using the Gemini API with an uploaded video file.
Media Resolution
The tokenization quality of images, videos and documents can be set for the whole request with GenerationConfig::$mediaResolution, or for a single part with Part::$mediaResolution. A lower resolution uses fewer tokens, a higher one lets the model see more detail. MEDIA_RESOLUTION_ULTRA_HIGH is only available per part.
Image Generation
Generate images with a Gemini image model. Use ImageConfig to set the aspect ratio and the image size (512, 1K, 2K or 4K, depending on the model).
Multi-turn Conversations (Chat)
Using Gemini, you can build freeform conversations across multiple turns. The chat session keeps the history and sends it with every message.
Chat with Streaming
You can also stream the response in a chat session. The history is automatically updated with the full response after the stream completes: text chunks are joined, while function calls, tool calls and thoughts are kept as separate parts, so they can be sent back to the model in the next turn.
Stream Generate Content
By default, the model returns a response after completing the entire generation process. You can achieve faster interactions by not waiting for the entire result, and instead use streaming to handle partial results.
Structured Output
Gemini generates unstructured text by default, but some applications require structured text. For these use cases, you can constrain Gemini to respond with JSON, a structured data format suitable for automated processing. You can also constrain the model to respond with one of the options specified in an enum.
JSON Schema
Instead of a Schema object, you can pass a JSON Schema as an array with responseJsonSchema. In that case, leave responseSchema out.
An empty PHP array is encoded as a JSON list. Use new \stdClass where the schema needs an empty JSON object, e.g. 'properties' => new \stdClass.
Function Calling
Gemini provides the ability to define and utilize custom functions that the model can call during conversations. This enables the model to perform specific actions or calculations through your defined functions.
Thinking models return a thoughtSignature with the function call part. The chat session keeps it in the history and sends it back automatically. If you manage the history yourself, send the model's parts back unchanged.
Function parameters can also be described with a JSON Schema array instead of a Schema object:
Multimodal function responses
A function response can contain images or documents in parts, so the model can look at what your function returned.
Code Execution
Gemini models can generate and execute code automatically, and return the result to you. This is useful for tasks that require computation, data manipulation, or other programmatic operations.
Grounding with Google Search
Grounding with Google Search connects the Gemini model to real-time web content and works with all available languages. This allows Gemini to provide more accurate answers and cite verifiable sources beyond its knowledge cutoff.
Use the GoogleSearch tool, which automatically handles search queries:
Grounding with Google Maps
Grounding with Google Maps allows the model to utilize real-world geographical data. This enables more precise location-based responses, such as finding nearby points of interest.
Grounding with File Search
Grounding with File Search enables the model to retrieve and utilize information from documents in your file search stores. This is useful for answering questions based on private or extensive document collections.
URL Context
The URL context tool lets the model read the content of URLs in your prompt.
Server-side Tool Invocations
Built-in tools (Google Search, Google Maps, URL context and File Search) are executed by the API. Set includeServerSideToolInvocations to receive these calls and their results as toolCall and toolResponse parts. The chat session sends them back automatically in the next turn.
This requires a model that supports it, such as the Gemini 3 models. Other models reject the request with an ErrorException.
Since the response contains several parts, read them with parts() instead of text().
System Instructions
System instructions let you steer the behavior of the model based on your specific needs and use cases. You can set the role and personality of the model, define the format of responses, and provide goals and guardrails for model behavior.
You can also combine system instructions with other features:
Speech Generation
Gemini allows generating speech from a text. To use that, make sure to use a model that supports this functionality. The model will output a base64 encoded audio string.
Single speaker
The audio is raw PCM. To play it, add a WAV header or convert it, e.g. ffmpeg -f s16le -ar 24000 -ac 1 -i audio.pcm audio.wav.
Multi speaker
Thinking Mode
Thinking models reason before they answer. Use ThinkingConfig to control how much they think and to receive summaries of their thoughts.
Gemini 2.5 models take a thinkingBudget (number of tokens), Gemini 3 models take a thinkingLevel.
Thinking tokens count towards maxOutputTokens. If the limit is too low, the model can stop before writing an answer, see Empty Responses.
Count Tokens
When using long prompts, it might be useful to count tokens before sending any content to the model.
Response Metadata
Besides the generated content, a response contains information about the request.
Configuration
Every prompt you send to the model includes parameter values that control how the model generates a response. The model can generate different results for different parameter values. Learn more about model parameters.
Also, you can use safety settings to adjust the likelihood of getting responses that may be considered harmful. Learn more about safety settings.
When using tools like GoogleMaps, you may also provide additional configuration via ToolConfig, such as RetrievalConfig for geographical context. See Grounding with Google Maps.
File Management
The File API lets you store up to 20 GB of files per project, with a per-file maximum size of 2 GB. Files are stored for 48 hours and can be accessed in API calls.
File Upload
To reference larger files and videos with various prompts, upload them to Gemini storage.
List Files
List all uploaded files in your project.
Get File Metadata
Retrieve metadata for a specific file. It accepts the file ID, the file name or the full URI.
Delete File
Delete a file from Gemini storage. It accepts the file ID, the file name or the full URI.
Cached Content
Context caching allows you to save and reuse precomputed input tokens for frequently used content. This reduces costs and latency for requests with large amounts of shared context. The content has to meet a minimum token count to be cached.
Create Cached Content
Cache content that you'll reuse across multiple requests.
List Cached Content
List all cached content in your project.
Get Cached Content
Retrieve a specific cached content by name.
Update Cached Content
Update the expiration time of cached content.
Delete Cached Content
Delete cached content when no longer needed.
Use Cached Content
Use cached content in your requests to save tokens and reduce latency.
File Search Stores
A file search store holds documents that the model can search with the File Search tool.
Create File Search Store
Create a file search store.
Get File Search Store
Get a specific file search store by name.
List File Search Stores
List all file search stores.
Delete File Search Store
Delete a file search store by name. Set force to also delete the documents in it.
File Search Documents
Upload File Search Document
Upload a local file directly to a file search store. Custom metadata can be used to filter documents with metadataFilter in the File Search tool. Values can be strings, numbers or lists of strings.
Import File Search Document
Import a file that was uploaded with the File API into a file search store.
Get Operation
Uploading and importing are long-running operations. Poll the operation until it is done.
Get File Search Document
Get a specific file search document by name.
List File Search Documents
List all file search documents within a store.
Delete File Search Document
Delete a file search document by name.
Embeddings
Embedding is a technique used to represent information as a list of floating point numbers in an array. With Gemini, you can represent text (words, sentences, and blocks of text) in a vectorized form, making it easier to compare and contrast embeddings. For example, two texts that share a similar subject matter or sentiment should have similar embeddings, which can be identified through mathematical comparison techniques such as cosine similarity.
Use an embedding model such as gemini-embedding-001 with either embedContent or batchEmbedContents:
Models
We recommend checking Google documentation for the latest supported models.
List Models
Use list models to see the available Gemini models programmatically:
-
pageSize (optional): The maximum number of Models to return (per page).
If unspecified, 50 models will be returned per page. This method returns at most 1000 models per page, even if you pass a larger pageSize. - nextPageToken (optional):
A page token, received from a previous models.list call.
Provide the pageToken returned by one request as an argument to the next request to retrieve the next page. When paginating, all other parameters provided to models.list must match the call that provided the page token.
Get Model
Get information about a model, such as version, display name, input token limit, etc.
Troubleshooting
Error Handling
Errors returned by the API throw a Gemini\Exceptions\ErrorException, with the message, status and code of the API error. Other failures, such as network errors, throw a Gemini\Exceptions\TransporterException, and a response that is not valid JSON throws a Gemini\Exceptions\UnserializableResponse.
Rate limit (429) and overload (503) errors are usually temporary and can be retried after a short wait.
Empty Responses
text() and parts() throw a ValueError when the response has no content. The error message contains the reason, which is also available on the response:
A common cause is MAX_TOKENS with thinking models: the thoughts use the whole maxOutputTokens budget before the answer is written. Increase maxOutputTokens or lower the thinking budget or level.
Timeout
You may run into a timeout when sending requests to the API. The default timeout is 30 seconds.
You can change it with the GEMINI_REQUEST_TIMEOUT environment variable:
Or in the config/gemini.php file:
Testing
The package provides a fake implementation of the client that allows you to fake the API responses.
To test your code, call Gemini::fake() in your test case. It swaps the client behind the facade for a fake that returns the given responses.
The fake responses are returned in the order they are provided while creating the fake client.
All responses have a fake() method that creates a response object from only the parameters relevant to your test case.
In case of a streamed response you can optionally provide a resource holding the fake response data.
Chats started with startChat() work with the fake as well. Each message is sent as a generateContent (or streamGenerateContent) request with the full history, and consumes the next fake response.
After the requests have been sent, use the assertion methods to check that the expected requests were sent:
Calls that configure a model, like withGenerationConfig(), withTool() or startChat(), are recorded as function calls:
To test a failing request, provide a Throwable as the response.
All versions of laravel with dependencies

google-gemini-php/client Version ^2.0
laravel/framework Version ^9.0|^10.0|^11.0|^12.0|^13.0